
Moving my Blog from Strapi to Markdown in Git
When I launched this blog in late 2024 it ran on Astro and a self-hosted Strapi. The Strapi part is gone.
The CMS was something I only paid attention to when it broke.
What I was actually running
For four published articles, twelve portfolio entries and ten FAQ answers, I was maintaining:
- a self-hosted Strapi instance on its own subdomain
- the database behind it
- an S3 bucket for images
- an admin application with its own login
- and an upgrade treadmill, because a CMS you self-host is a CMS you have to keep patching
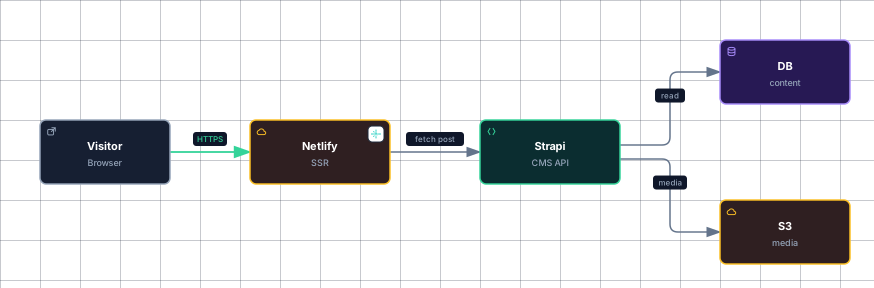
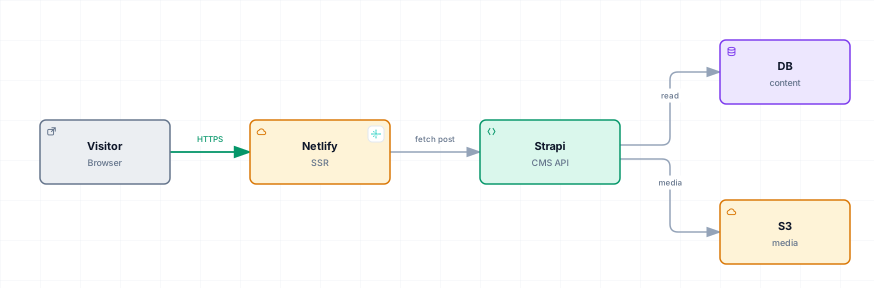
For a single-author site that is a lot of moving parts to store what amounts to twenty-six documents. None of it was earning its keep. I was not collaborating with anyone through the admin UI. I was not scheduling content. I was writing in a text box in a browser instead of in my editor.
It was hitting the CMS on every request
I had assumed the content was fetched at build time and baked into the output. It was not.
Four routes, the home page, /blog, /portfolio and /faqs, were server-rendered on Netlify with no prerender flag, which meant they called the CMS on every single request. My blog's availability was tied to my Strapi instance's availability. If the CMS went down, or the database did, or I fumbled an upgrade, the site would be broken for every visitor.
I had been running that way since launch without realising it. That's what made me actually want to do this, not just think about it.
Seven articles I had forgotten I wrote
Strapi has a Draft & Publish feature, and I had used it. When I audited the API before touching anything, I found seven finished, unpublished articles sitting in the database since the blog's first months: real bodies, real excerpts, hero images and all. I had written them, not published them, and completely forgotten they existed.
Had I just exported the published content and torn the CMS down, all seven would have gone into the bin with the database. They are now in git as markdown with draft: true, which means they cost nothing, they are visible to me every time I open the content folder, and I can publish any of them by changing one word.
One of them turned out to be an earlier version of an article I had already published, same opening sentence, same closing question, same hero image. That one is staying unpublished. But the other six are genuinely things I might finish.
The migration itself
The goal I set was strict: the rendered HTML should not change. Same output, byte for byte, apart from a written-down list of differences I had explicitly decided were acceptable.
So before changing anything I captured the live HTML of every route, and then compared the new output against it.
SmartyPants would have quietly rewritten my prose
Astro's markdown pipeline enables SmartyPants by default. The old renderer did not. Left alone, the migration would have converted every straight apostrophe to a curly one and every double hyphen to an en dash, 57 apostrophes across the corpus, and every one of those would have shown up in the diff as noise, hiding anything real underneath.
One line of config turns it off. Finding out that it needed to be the first line of config, before any comparison was run, took longer.
markdown: {
  smartypants: false,
}
The check that was passing by doing nothing
This is the one I am most glad I caught.
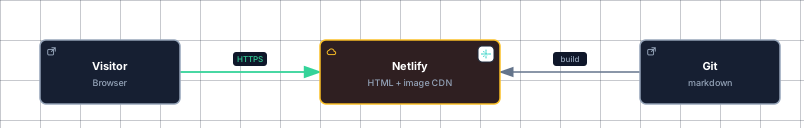
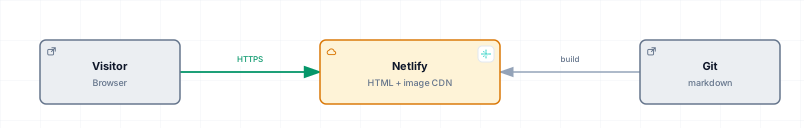
Content images used to be served straight from S3 at full size, around 2.3 MB of unoptimised originals shipped to every visitor. After the migration they became local assets going through Netlify's image CDN, which resizes and re-encodes them. To prove that actually worked in production I wrote a check that scraped every image URL from every page and requested it, asserting a 200, a modern content type and a payload smaller than the source.
It found 44 URLs and passed all of them. It should have found 28.
The scraper decoded & but not &, which is the form most of those URLs are actually written in. So the same image appeared in the set twice under two spellings. That alone would only have inflated a number, but the undecoded copy was worse than useless. curl reads the # as the start of a URL fragment and throws away everything after it, so the request that reached the CDN had no width or height on it at all. The CDN did the only sensible thing and returned the full-size image, with a 200 and a perfectly modern content type.
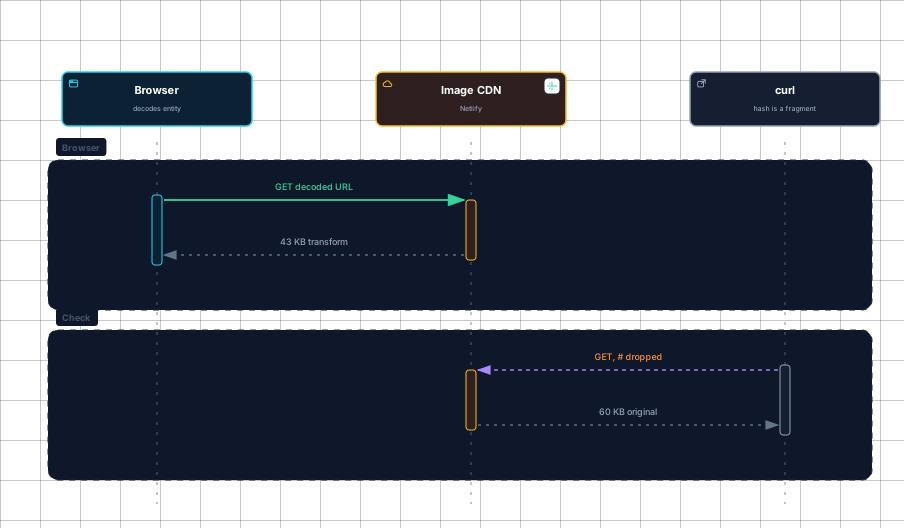
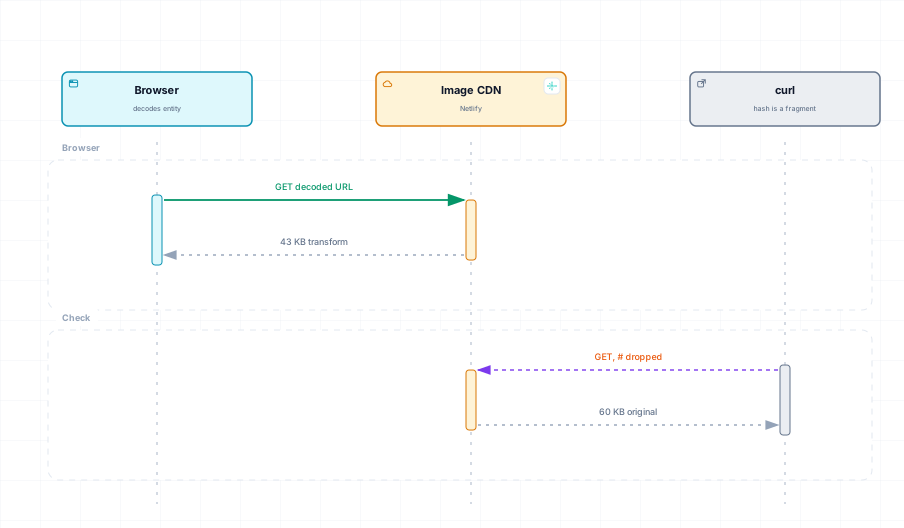
Sixteen unresized images were being counted as passes by the check whose entire purpose was to catch unresized images. 60 KB coming back where the real transform is 43 KB, and a green tick next to it.
Browsers decode the entity before making the request, so real visitors were always getting the correct image. The pages were fine. The check was lying, and it was lying in the most dangerous direction available to a check, telling me something was verified when it had verified nothing.
The question I now ask of any check: could this come back green because it looked at nothing? If yes, it should fail instead.
Where it landed
Content lives in src/content as markdown files with frontmatter, one folder per entry, hero image sitting next to the article that uses it. The site has no runtime dependency on anything but itself. I deleted the environment variable pointing at the CMS and the build did not notice.
A post folder looks like this:
src/content/blog/moving-my-blog-from-strapi-to-markdown/
  index.md
  moving-my-blog-from-strapi-to-markdown-hero.jpg
What I actually enjoy about it now:
- Writing in my editor. Obvious in hindsight.
- Content changes are diffs. I can see exactly what changed in an article, when, and why, in the same history as the code.
- The images got faster for free. Portfolio thumbnails used to download the full-size original to render at 320 pixels wide. One of them was a 4000×3000 PNG.
- Coding agents can edit it directly. Content in git is content an agent can read, edit and open a pull request against, with no API shim in between.
If you have people who are not developers writing your content, a CMS is doing real work for you and this is the wrong trade. Strapi remains a genuinely good piece of software. My launch-day self was not wrong to like it.
But if you are one person, writing occasionally, and every one of your content editors already lives in a code editor, then the database, the admin app, the bucket and the upgrade treadmill are all overhead paid for a workflow you are not using.
Cheers! 🍺